
4shared Scrapper 01-21-2022, 05:47 AM
#1
Hey everyone,
browsing around I saw a post detailing the best hosting websites and saw one that I recognized. Some months ago a friend of mine asked me to make him a scrapper for 4shared, the motivation behind it had very little to do with good morals. Other than for sharing things, 4shared seems to be a popular tool in some countries to backup information, specially from phones, so you can imagine the type of content some people share by mistake (I think the site makes your folder shared or available in the global search by default, bad combination).
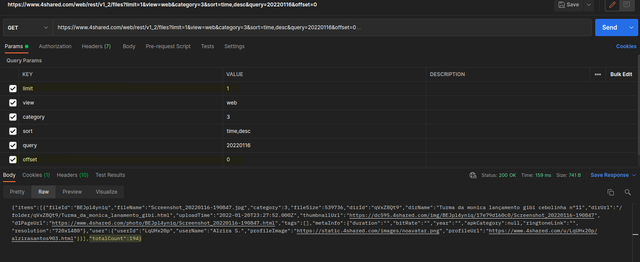
My friend was tired of browsing the site manually and also wanted to get around the 84 (I think) page limit to their pagination. So I forced myself into their API and the result is this python3 file that using CLI asks you about the search you want to make, and then calls their API directly. When you no longer want to scrape or when the query is done, it creates 2 files in your computer: a JSON file and an HTML file! The JSON file is just a stripped down version of the result with the data we care about, and the HTML is just an easier way to access this information.
Download:
https://www.4shared.com/s/fAW6k3Rwiiq hosted by 4shared because it would be no fun to share it elsewhere.
Requirements
Setting Up
In order to use the script, 3 libraries are required: json2table, PyInquirer and requests. If you don't want to pip install them manually, go to the folder where you unpacked the files and run the following command (as long as you have the requirements.txt that I included):
Do note that there are 2 folders inside the archive, JSON and HTML. That's where the files will be sent to, if they don't exist you might face errors.
Usage
The script is really simple to use, after navigating to the folder where the file is, run it by using the following command in your terminal:
The script has a built in very simple to use menu, here's some examples:
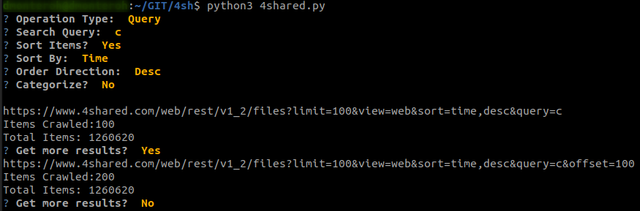
By selecting the option "Query" you can input the text you want to search for. However, you can leave it empty, 4shared allows for it.
Then there's the sorting options, this is the sorting that 4shared does from the serverside. If you want to see the newest files, then I recommend you sort by time, and order descending.
Finally, there's the categorization option, allowing you to specify what kind of file you want to search (Images, Video, Archives, Books, Music, Apps or All Types).
When you are scrapping by Query, the program will ask you every "100" items if you would like to search for 100 more. At the time, automatically scrapping all items was out of scope since my friend didn't want to browse through thousands of (old) results.
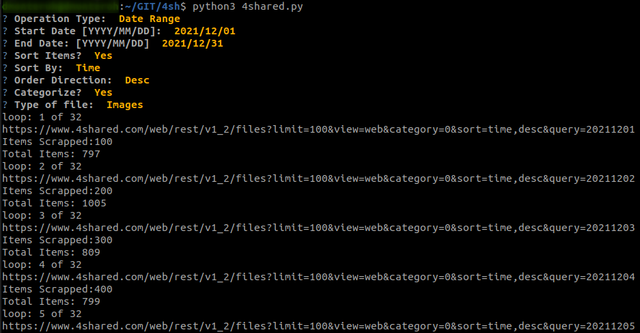
The second option is Date Range. Remember that many people automatically backup their phones to 4shared? Well, images, videos and other kinds of data are usually stored in the phone with the current date as the file name. Do you want to see the 100 newest files uploaded corresponding to each day between December 1st and December 31st? My friend sure did.
And the results?
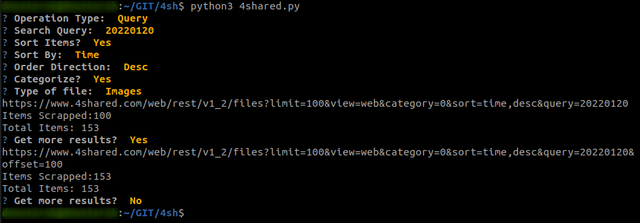
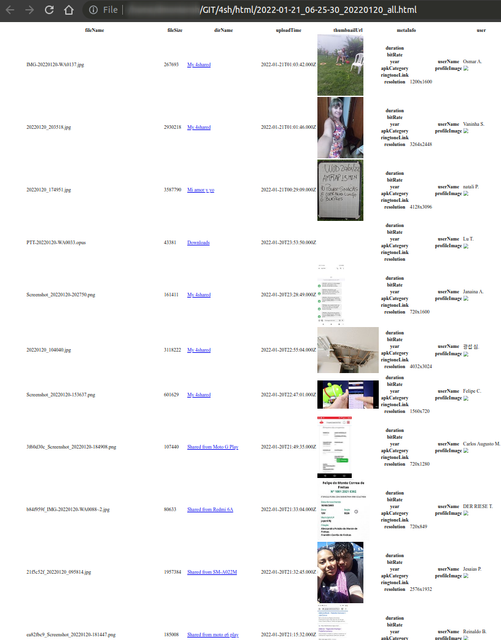
(zoomed out to get more results in the image, also, the 4th image from the bottom is a screenshot of what seems like someone asking for a credit to buy a motorcycle)
You can see the thumbnails for Images and Videos. If the file is in a public folder, you will be able to click the folder name to access it.
If there is no folder to go to, I trust that you will find a way to see the bigger version of the file yourself at least if it's an image it should be simple enough
Other Notes
What does this mean for you? Well, my friend basically scrapes 4shared a couple of times a weeks to see what interesting things he finds. Just a heads up, it is likely sensitive and/or private information, like screenshots of passwords, conversations, private pictures and documents. I am not responsible for the use anyone gives this script, as it was made and shared for educational purposes.
If you are savvy enough, you might even be able to extend the code to automate some other behaviors.
Edit: Big thanks to fritz for helping with debugging and suggesting fixes
Have fun scrapping!
QUICK HEADS UP, I HAVEN'T EXECUTED THIS SCRIPT IN WINDOWS, BUT IT SHOULD WORK
browsing around I saw a post detailing the best hosting websites and saw one that I recognized. Some months ago a friend of mine asked me to make him a scrapper for 4shared, the motivation behind it had very little to do with good morals. Other than for sharing things, 4shared seems to be a popular tool in some countries to backup information, specially from phones, so you can imagine the type of content some people share by mistake (I think the site makes your folder shared or available in the global search by default, bad combination).
My friend was tired of browsing the site manually and also wanted to get around the 84 (I think) page limit to their pagination. So I forced myself into their API and the result is this python3 file that using CLI asks you about the search you want to make, and then calls their API directly. When you no longer want to scrape or when the query is done, it creates 2 files in your computer: a JSON file and an HTML file! The JSON file is just a stripped down version of the result with the data we care about, and the HTML is just an easier way to access this information.
Download:
https://www.4shared.com/s/fAW6k3Rwiiq hosted by 4shared because it would be no fun to share it elsewhere.
Requirements
- Python3 & PIP
Setting Up
In order to use the script, 3 libraries are required: json2table, PyInquirer and requests. If you don't want to pip install them manually, go to the folder where you unpacked the files and run the following command (as long as you have the requirements.txt that I included):
Code:
pip3 install -r requirements.txtUsage
The script is really simple to use, after navigating to the folder where the file is, run it by using the following command in your terminal:
Code:
python3 4shared.pyBy selecting the option "Query" you can input the text you want to search for. However, you can leave it empty, 4shared allows for it.
Then there's the sorting options, this is the sorting that 4shared does from the serverside. If you want to see the newest files, then I recommend you sort by time, and order descending.
Finally, there's the categorization option, allowing you to specify what kind of file you want to search (Images, Video, Archives, Books, Music, Apps or All Types).
When you are scrapping by Query, the program will ask you every "100" items if you would like to search for 100 more. At the time, automatically scrapping all items was out of scope since my friend didn't want to browse through thousands of (old) results.
The second option is Date Range. Remember that many people automatically backup their phones to 4shared? Well, images, videos and other kinds of data are usually stored in the phone with the current date as the file name. Do you want to see the 100 newest files uploaded corresponding to each day between December 1st and December 31st? My friend sure did.
And the results?
(zoomed out to get more results in the image, also, the 4th image from the bottom is a screenshot of what seems like someone asking for a credit to buy a motorcycle)
You can see the thumbnails for Images and Videos. If the file is in a public folder, you will be able to click the folder name to access it.
If there is no folder to go to, I trust that you will find a way to see the bigger version of the file yourself
at least if it's an image it should be simple enoughOther Notes
What does this mean for you? Well, my friend basically scrapes 4shared a couple of times a weeks to see what interesting things he finds. Just a heads up, it is likely sensitive and/or private information, like screenshots of passwords, conversations, private pictures and documents. I am not responsible for the use anyone gives this script, as it was made and shared for educational purposes.
If you are savvy enough, you might even be able to extend the code to automate some other behaviors.
Edit: Big thanks to fritz for helping with debugging and suggesting fixes
Have fun scrapping!
QUICK HEADS UP, I HAVEN'T EXECUTED THIS SCRIPT IN WINDOWS, BUT IT SHOULD WORK
(This post was last modified: 01-21-2022, 01:32 PM by dnks.
Edit Reason: Windows user warning
)