
+- Sinisterly (https://sinister.li)
+-- Forum: Hacking (https://sinister.li/Forum-Hacking)
+--- Forum: Hacking Tools (https://sinister.li/Forum-Hacking-Tools)
+--- Thread: 4shared Scrapper (/Thread-4shared-Scrapper)
Pages:
1
2
4shared Scrapper - dnks - 01-21-2022
Hey everyone,
browsing around I saw a post detailing the best hosting websites and saw one that I recognized. Some months ago a friend of mine asked me to make him a scrapper for 4shared, the motivation behind it had very little to do with good morals. Other than for sharing things, 4shared seems to be a popular tool in some countries to backup information, specially from phones, so you can imagine the type of content some people share by mistake (I think the site makes your folder shared or available in the global search by default, bad combination).
My friend was tired of browsing the site manually and also wanted to get around the 84 (I think) page limit to their pagination. So I forced myself into their API and the result is this python3 file that using CLI asks you about the search you want to make, and then calls their API directly. When you no longer want to scrape or when the query is done, it creates 2 files in your computer: a JSON file and an HTML file! The JSON file is just a stripped down version of the result with the data we care about, and the HTML is just an easier way to access this information.
Download:
https://www.4shared.com/s/fAW6k3Rwiiq hosted by 4shared because it would be no fun to share it elsewhere.
Requirements
- Python3 & PIP
Setting Up
In order to use the script, 3 libraries are required: json2table, PyInquirer and requests. If you don't want to pip install them manually, go to the folder where you unpacked the files and run the following command (as long as you have the requirements.txt that I included):
Code:
pip3 install -r requirements.txtUsage
The script is really simple to use, after navigating to the folder where the file is, run it by using the following command in your terminal:
Code:
python3 4shared.py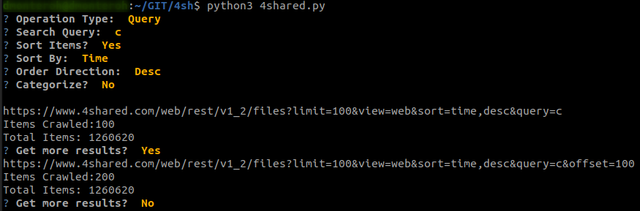
By selecting the option "Query" you can input the text you want to search for. However, you can leave it empty, 4shared allows for it.
Then there's the sorting options, this is the sorting that 4shared does from the serverside. If you want to see the newest files, then I recommend you sort by time, and order descending.
Finally, there's the categorization option, allowing you to specify what kind of file you want to search (Images, Video, Archives, Books, Music, Apps or All Types).
When you are scrapping by Query, the program will ask you every "100" items if you would like to search for 100 more. At the time, automatically scrapping all items was out of scope since my friend didn't want to browse through thousands of (old) results.
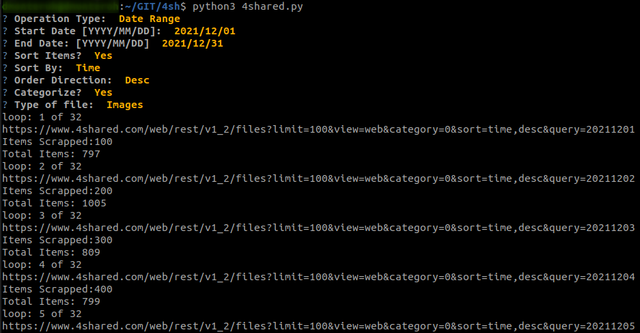
The second option is Date Range. Remember that many people automatically backup their phones to 4shared? Well, images, videos and other kinds of data are usually stored in the phone with the current date as the file name. Do you want to see the 100 newest files uploaded corresponding to each day between December 1st and December 31st? My friend sure did.
And the results?
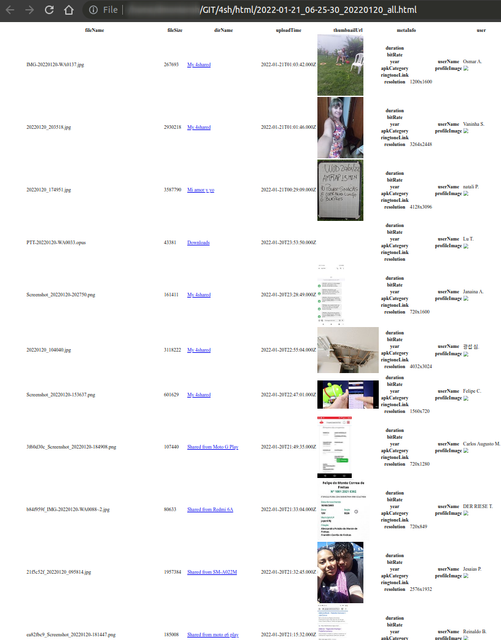
(zoomed out to get more results in the image, also, the 4th image from the bottom is a screenshot of what seems like someone asking for a credit to buy a motorcycle)
You can see the thumbnails for Images and Videos. If the file is in a public folder, you will be able to click the folder name to access it.
If there is no folder to go to, I trust that you will find a way to see the bigger version of the file yourself
 at least if it's an image it should be simple enough
Other Notes
What does this mean for you? Well, my friend basically scrapes 4shared a couple of times a weeks to see what interesting things he finds. Just a heads up, it is likely sensitive and/or private information, like screenshots of passwords, conversations, private pictures and documents. I am not responsible for the use anyone gives this script, as it was made and shared for educational purposes.
If you are savvy enough, you might even be able to extend the code to automate some other behaviors.
Edit: Big thanks to fritz for helping with debugging and suggesting fixes
Have fun scrapping!
QUICK HEADS UP, I HAVEN'T EXECUTED THIS SCRIPT IN WINDOWS, BUT IT SHOULD WORK
RE: 4shared Scrapper - mothered - 01-21-2022
One fine contribution.
I see you've put a lot of effort Into It, which Is why It serves Its purpose as written.
RE: 4shared Scrapper - dnks - 01-21-2022
(01-21-2022, 09:42 AM)mothered Wrote: One fine contribution.Haha thanks, I'm usually very shy when sharing code. I think it's mostly because small scripts like this one aren't really planned or designed, between the conception a few months back and cleaning a bit of code before posting it here, I have to admit that I rushed it a bit? This is around ~1hr of code? Maybe less, and it generates worries about people not liking it, or code failing. Wouldn't surprise me if anyone downloaded it and it crashed right away lmao
I see you've put a lot of effect Into It, which Is why It serves Its purpose as written.
RE: 4shared Scrapper - mothered - 01-21-2022
(01-21-2022, 09:48 AM)dnks Wrote: Wouldn't surprise me if anyone downloaded it and it crashed right away lmaoAre you saying that, because the tool was rushed, or you're aware of some Inconsistencies with the code?
RE: 4shared Scrapper - dnks - 01-21-2022
Since it's not a big system, no time was spent planning it or making it particularly straightforward to expand on, and I also didn't add a single line of comments explaining what I did. I haven't tested it on Windows, the support added for Windows was literally me just making educated guesses. Although I am sure my friend uses it quite often, I know he realistically just uses one of the use cases.
It's mostly being used to work on more professional CI environments and designing for hours before writing a single line of code that makes me doubt my quickly put together scripts.
Partly posting it so other people use it, and if it does fail, they will say something so I can improve it
RE: 4shared Scrapper - fritz - 01-21-2022
Nice of you sharing this, thanks!
(01-21-2022, 09:48 AM)dnks Wrote: I have to admit that I rushed it a bit? This is around ~1hr of code? Maybe less, and it generates worries about people not liking it, or code failing. Wouldn't surprise me if anyone downloaded it and it crashed right away lmaoFortunately you (usually) can't go (too) wrong with python
Although I did find few issues (with my env at least, python 3.9.7 / linux)
- category search didn't work as you're using the val.lower() filter in the prompt
- category naming of the json file didn't work as you're using hasattr on a dict
I fixed those, if anyone is interested here is the diff:
Spoiler:
Code:
37,43c37,43
<            'All':0,
<            'Music':1,
<            'Video':2,
<            'Images':3,
<            'Archives':4,
<            'Books':5,
<            'Apps':8,
---
>            'all':0,
>            'music':1,
>            'video':2,
>            'images':3,
>            'archives':4,
>            'books':5,
>            'apps':8,
45c45
<        return switcher.get(name, 0)
---
>        return switcher.get(name.lower(), 0)
188c188
<        if self.answers['isType'] == True and hasattr(self.typeAnswers, 'categoryText'):
---
>        if self.answers['isType'] == True and 'categoryText' in self.typeAnswers:
249d248
<
RE: 4shared Scrapper - dnks - 01-21-2022
Yeah I was expecting something like that to happen, thank you for debugging :')

I've applied your changes and updated the file, same download link, and was lucky enough to have caught it while being in windows, I'm a bit more confident on the script now. Happy scrapping
RE: 4shared Scrapper - fritz - 01-21-2022
One more thing I noticed (sorry haha), Total items doesn't increment after the first try. And also there's no link to the original post, so only thumbnail is shown when the folder isn't public..
(well ok that's 2 ^^)
Here is my fix
Spoiler:
Code:
169c169
<                self.totalCount = int(r.json()['totalCount'])
---
>                self.totalCount += int(r.json()['totalCount'])
228c228
<            res['thumbnailUrl'] = "<img src='"+res['thumbnailUrl']+"'>"
---
>            res['thumbnailUrl'] = "<a href='"+res['d1PageUrl']+"'><img src='"+res['thumbnailUrl']+"'></a>"
EDIT: Looks like there are also some sort of honeypot there https://www.4shared.com/folder/MpiwvqZt/_online.html?detailView=false&sortAsc=true&sortsMode=NAME
RE: 4shared Scrapper - dnks - 01-21-2022
Well, in the case of the totalCount, that's actually what the 4shared pagination API returns. It's the total number of results that exist for that query, so that totalCount shouldn't increase, I'm printing it so that you can tell when you've reached the maximum amount of items.
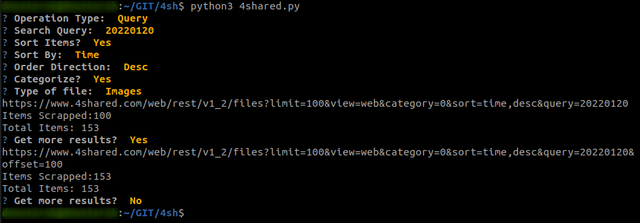
A way to test this is to query for 20220116 for images, I'm expecting it to not have many images since it's a very recent date. The offset is going to show you the current amount of items you've scrapped (100 because that's the max items per request) and the totalCount shouldn't change even when you call it again, it's the same amount items available in the page.

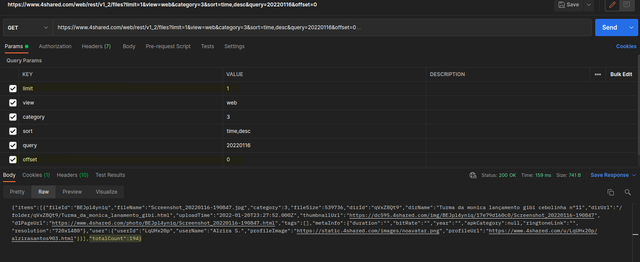
wanted to show it in curl originally but was hard to read. Even if you add offset, the totalCount doesn't change
As for the thumbnail, yeah, you're right, that was just lazy of me
~~
And about the honeypot, that looks like the backup from an scammer from india, and also kinda old, april 2021 kinda outdated

RE: 4shared Scrapper - fritz - 01-21-2022
(01-21-2022, 04:23 PM)dnks Wrote: Well, in the case of the totalCount, that's actually what the 4shared pagination API returns. It's the total number of results that exist for that query, so that totalCount shouldn't increase, I'm printing it so that you can tell when you've reached the maximum amount of items.
A way to test this is to query for 20220116 for images, I'm expecting it to not have many images since it's a very recent date. The offset is going to show you the current amount of items you've scrapped (100 because that's the max items per request) and the totalCount shouldn't change even when you call it again, it's the same amount items available in the page.
Spoiler:
wanted to show it in curl originally but was hard to read. Even if you add offset, the totalCount doesn't change
I see, that wasn't very clear haha, my fix would be to stop when the same results are returned then but maybe another time ^^
(01-21-2022, 04:23 PM)dnks Wrote: As for the thumbnail, yeah, you're right, that was just lazy of meI don't know how your friend used it, that kinda sucks to have only the thumbnail when the folder is protected
(01-21-2022, 04:23 PM)dnks Wrote: And about the honeypot, that looks like the backup from an scammer from india, and also kinda old, april 2021 kinda outdatedI don't know if that's from a scammer but there are some odd stuff (empty btc wallets - that have been empty for 8 years mostly). Maybe if someone digs a bit they might find something useful, who knows :p