
+- Sinisterly (https://sinister.li)
+-- Forum: Hacking (https://sinister.li/Forum-Hacking)
+--- Forum: Hacking Tools (https://sinister.li/Forum-Hacking-Tools)
+--- Thread: dcrawl (/Thread-dcrawl)
dcrawl - ZanGetsu - 10-06-2017
dcrawl is a simple, but smart, multi-threaded web crawler for randomly gathering huge lists of unique domain names.
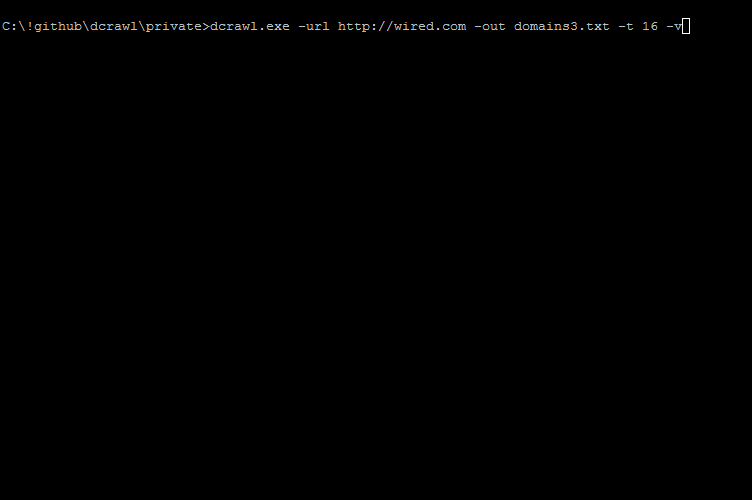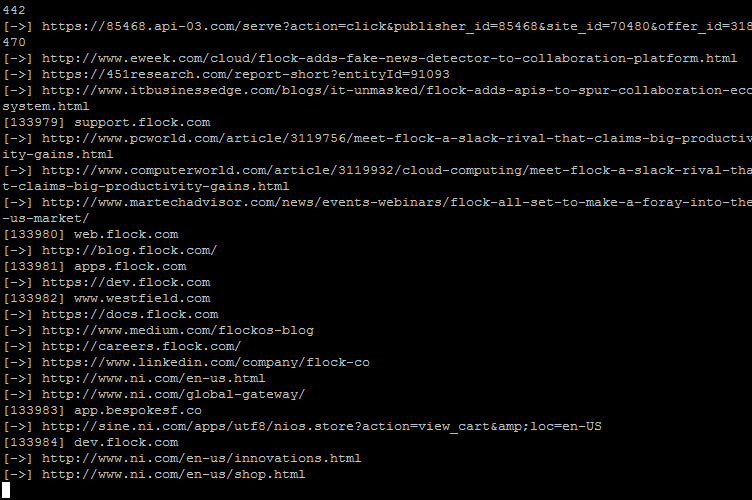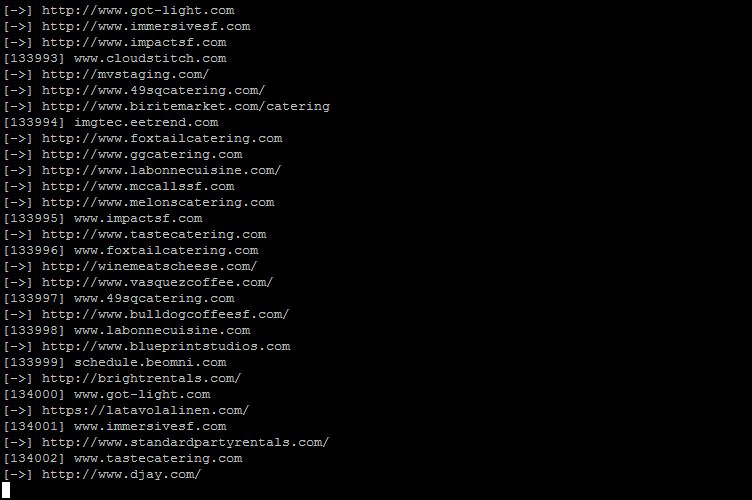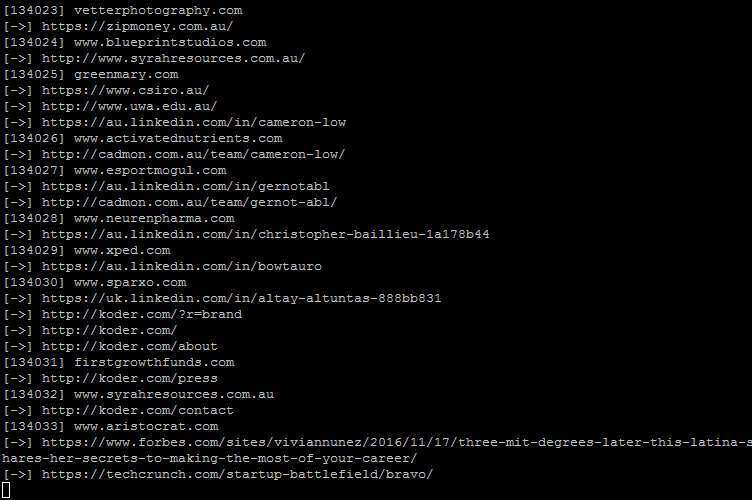
How it works?
dcrawl takes one site URL as input and detects all <a href=...> links in the site's body. Each found link is put into the queue. Successively, each queued link is crawled in the same way, branching out to more URLs found in links on each site's body.
How smart crawling works:
- Branching out only to predefined number of links found per one hostname.
- Maximum number of allowed different hostnames per one domain (avoids subdomain crawling hell e.g. blogspot.com).
- Can be restarted with same list of domains - last saved domains are added to the URL queue.
- Crawls only sites that return text/html Content-Type in HEAD response.
- Retrieves site body of maximum 1MB size.
- Does not save inaccessible domains.
Usage:
Code:
    ___                          __
  __| _/________________ __  _  _|  |
 / __ |/ ___\_  __ \__  \\ \/ \/ /  |
/ /_/ \  \___|  | \// __ \\     /|  |__
\____ |\___  >__|  (____  /\/\_/ |____/
     \/    \/           \/       v.1.0

usage: dcrawl -url URL -out OUTPUT_FILE -t THREADS

  -ms int
        maximum different subdomains for one domain (def. 10) (default 10)
  -mu int
        maximum number of links to spider per hostname (def. 5) (default 5)
  -out string
        output file to save hostnames to
  -t int
        number of concurrent threads (def. 8) (default 8)
  -url string
        URL to start scraping from
  -v bool
verbose (default false)RE: dcrawl - mothered - 10-06-2017
I like this feature. It'll certainly speed up the process and avoid useless sites.
Quote:Crawls only sites that return text/html Content-Type in HEAD response.
Good work.